
Browse our current openings and find a role that matches your skills and ambition.
Know more ▸
Get a feel for our culture, our people and the way we work together every day.
Know more ▸
Health, flexibility and growth benefits designed to support you and your family.
Know more ▸

Kickstart your career with hands-on internship opportunities and mentorship.
Know more ▸

Written by 3Shadz Editorial Team
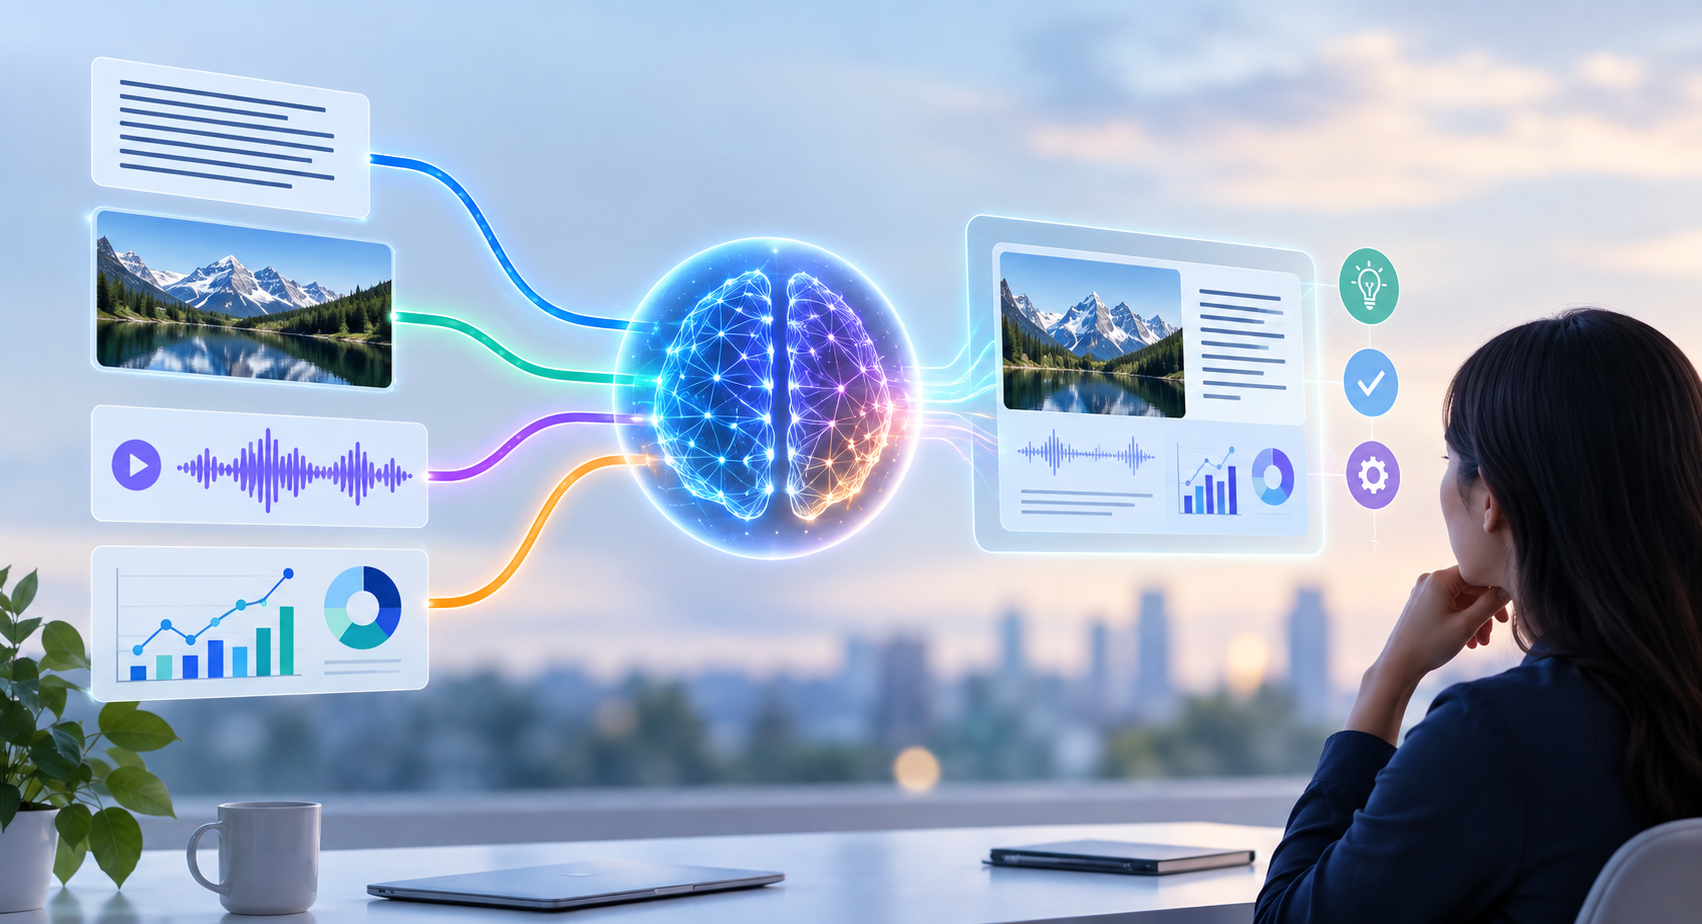
Human beings never take in the world one channel at a time. A radiologist reads a scan while listening to the patient and scanning the chart; a mechanic looks at a worn part, hears the noise it makes, and checks it against a manual. Yet for most of its history, AI was trained to do exactly one of those things (read text, classify an image, or transcribe speech) in isolation. Multimodal AI closes that gap by taking in several kinds of input at once and reasoning across them, unlocking tasks that no single-modality system can perform.
This article is written for technology and product leaders weighing where multiple input types earn their keep. It answers:
Put simply, a modality is a distinct type of input: a channel through which information arrives. Text is one modality; a photograph is another; recorded speech, video, and the structured rows of a database or sensor feed are others still. Each carries something the others do not. A product photo shows shape and color that words describe only clumsily; a written note captures intent and history that no image contains; the tone of a recorded call adds meaning a bare transcript flattens.
For years, models were specialists in a single channel. An image classifier could name what was in a picture but could not read the caption beside it; a language model could summarize a report yet stayed blind to the diagram on the page. That narrowness is the ceiling multimodal AI is built to break.
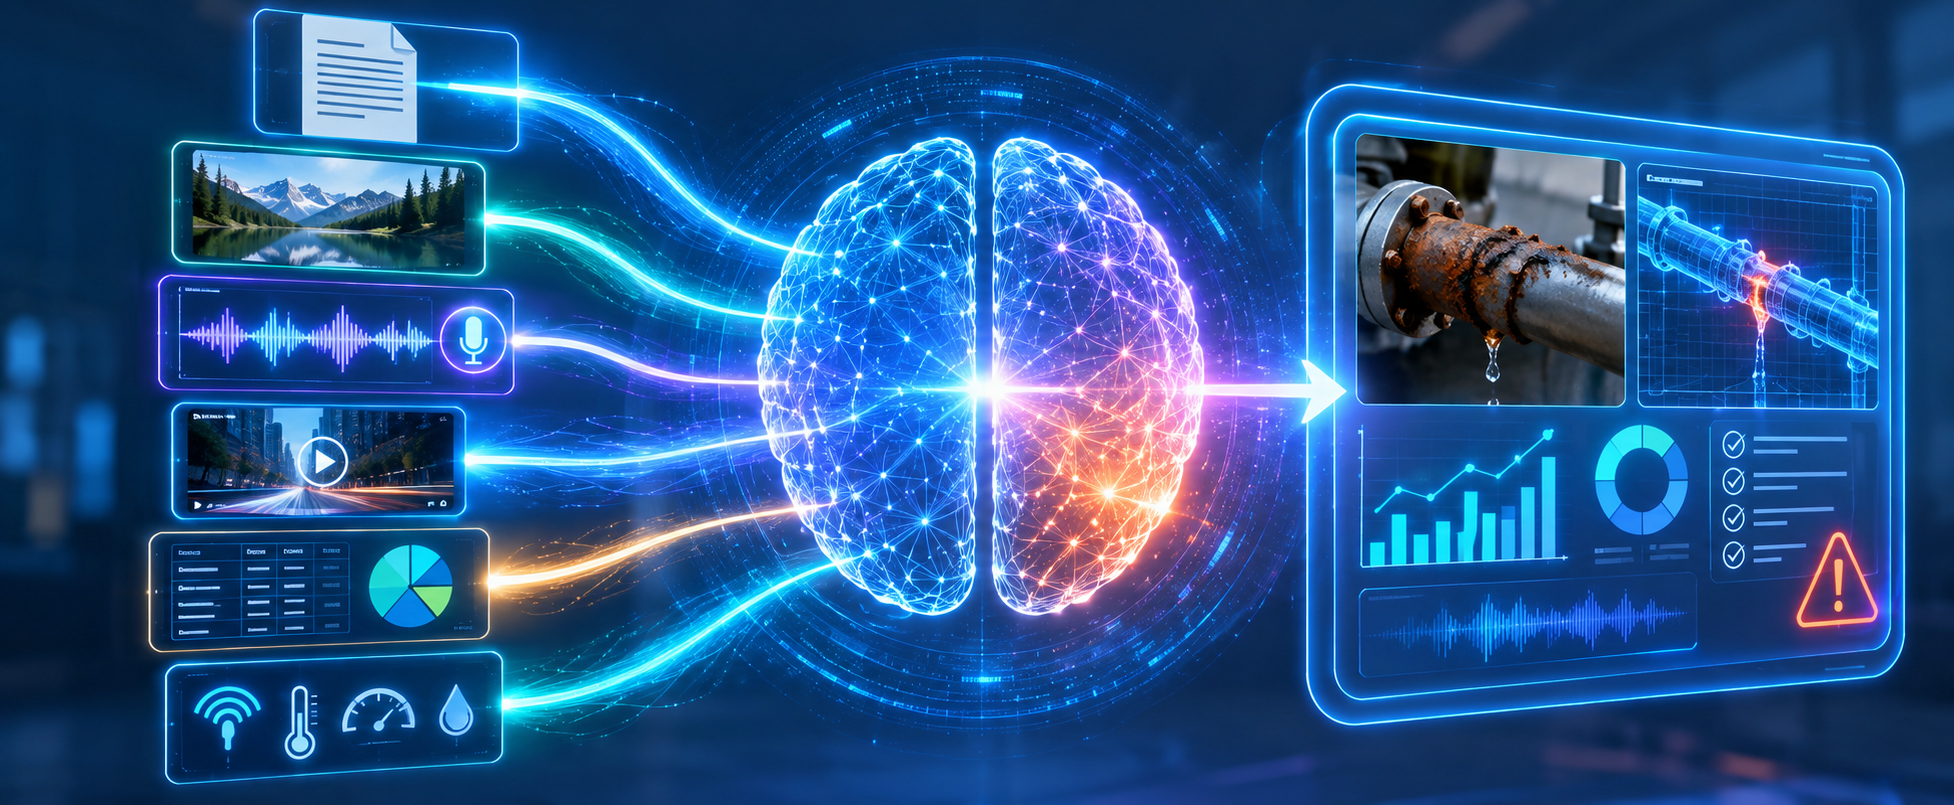
The point of multimodal AI is not to run several single-purpose models side by side and staple their outputs together. It is fusion, letting the model relate the inputs so that one informs the other. Consider a maintenance report that reads “it’s leaking” next to a photo of a corroded joint. Text alone leaves you guessing what and where; the image alone says nothing about the reported symptom. Read together, they pinpoint the problem. That mutual reinforcement is the whole game.
Nothing shows the payoff more plainly than work where the evidence naturally arrives in several forms at once.
A claimant uploads pictures of a damaged vehicle and a short written account. The model detects the affected panels in the images, matches them against the description, and flags where the two disagree, catching a note that describes rear damage when the photos clearly show the front.
On-site, a technician photographs an unfamiliar valve and asks a spoken question. The system identifies the part, retrieves the matching page from the equipment manual, and answers aloud, combining vision, a text knowledge base, and voice so the fix happens without hunting through a 400-page PDF.
Photographing a chair they like, a shopper types “something similar in oak, under $300.” The model reads the image for shape and style and the text for material and budget, returning matches that satisfy both: a request neither the picture nor the words could express alone.
During a recorded call, the model transcribes the audio while also reading the slides shared on screen. It links what was said to what was shown, then produces a summary and a task list that reference the right figures and owners: detail a transcript stripped of its visuals would garble.
Behind the interface, each modality is handled by a specialized encoder: one that turns images into numbers, another for audio, another for text. Their outputs are mapped into a shared representation space, a common numerical world where a photo of a dog and the word “dog” land close together. Once inputs live in that shared space, a single model can attend across all of them at once.
Systems differ mainly in when they fuse. Some combine inputs early and reason over everything jointly, which captures subtle cross-modal cues; others process each channel separately and merge the conclusions late, which is simpler and more robust when one input is missing or noisy. Neither is universally right: the choice follows the task and the quality of the data.
Multimodal AI is a class of models that accept and reason over more than one kind of input (such as text, images, audio, and structured data) within a single system. Instead of analyzing each input separately, it aligns them in a shared representation so it can answer questions that depend on several sources at once.
Generative AI describes what a model produces: new text, images, or code. Multimodal describes what it can take in and relate. The two overlap: many modern generative models are multimodal, able to read an image and write about it. But a multimodal system need not be generative: a model that matches a photo to the right manual page is multimodal without creating anything new.
If your task genuinely lives in one channel (classifying support emails, transcribing calls), a single-modality model is simpler, cheaper, and easier to evaluate. Reach for multimodal only when the answer depends on combining inputs, such as judging a photo against a written description. The value comes from the combination, not from adding modalities for their own sake.
Beyond the model, you need clean paired data to test against, encoders or an API that handle each input type, and a way to trace which modality drove a given answer. Cost, latency, and privacy planning matter more than with single-input systems, because every request carries several kinds of data at once.
Multimodal AI matters because real problems rarely arrive in a single format. A claim is photos and notes; a repair is a part, a manual, and a spoken question; a purchase is a picture and a preference. Systems that read only one of those channels leave the rest of the evidence on the table.
In practice, add a modality when the answer depends on the combination, and not a moment before. Fusion earns its cost where one input resolves what another leaves ambiguous, and adds only complexity where a single channel already holds the answer. Start where the cross-modal payoff is obvious, prove it on paired data you trust, and expand from there.
Start Your AI Journey
Whether you are exploring AI for the first time or scaling enterprise-wide initiatives, 3Shadz helps businesses design, develop, and deploy intelligent solutions that drive measurable results.