
Browse our current openings and find a role that matches your skills and ambition.
Know more ▸
Get a feel for our culture, our people and the way we work together every day.
Know more ▸
Health, flexibility and growth benefits designed to support you and your family.
Know more ▸

Kickstart your career with hands-on internship opportunities and mentorship.
Know more ▸

Written by 3Shadz Editorial Team
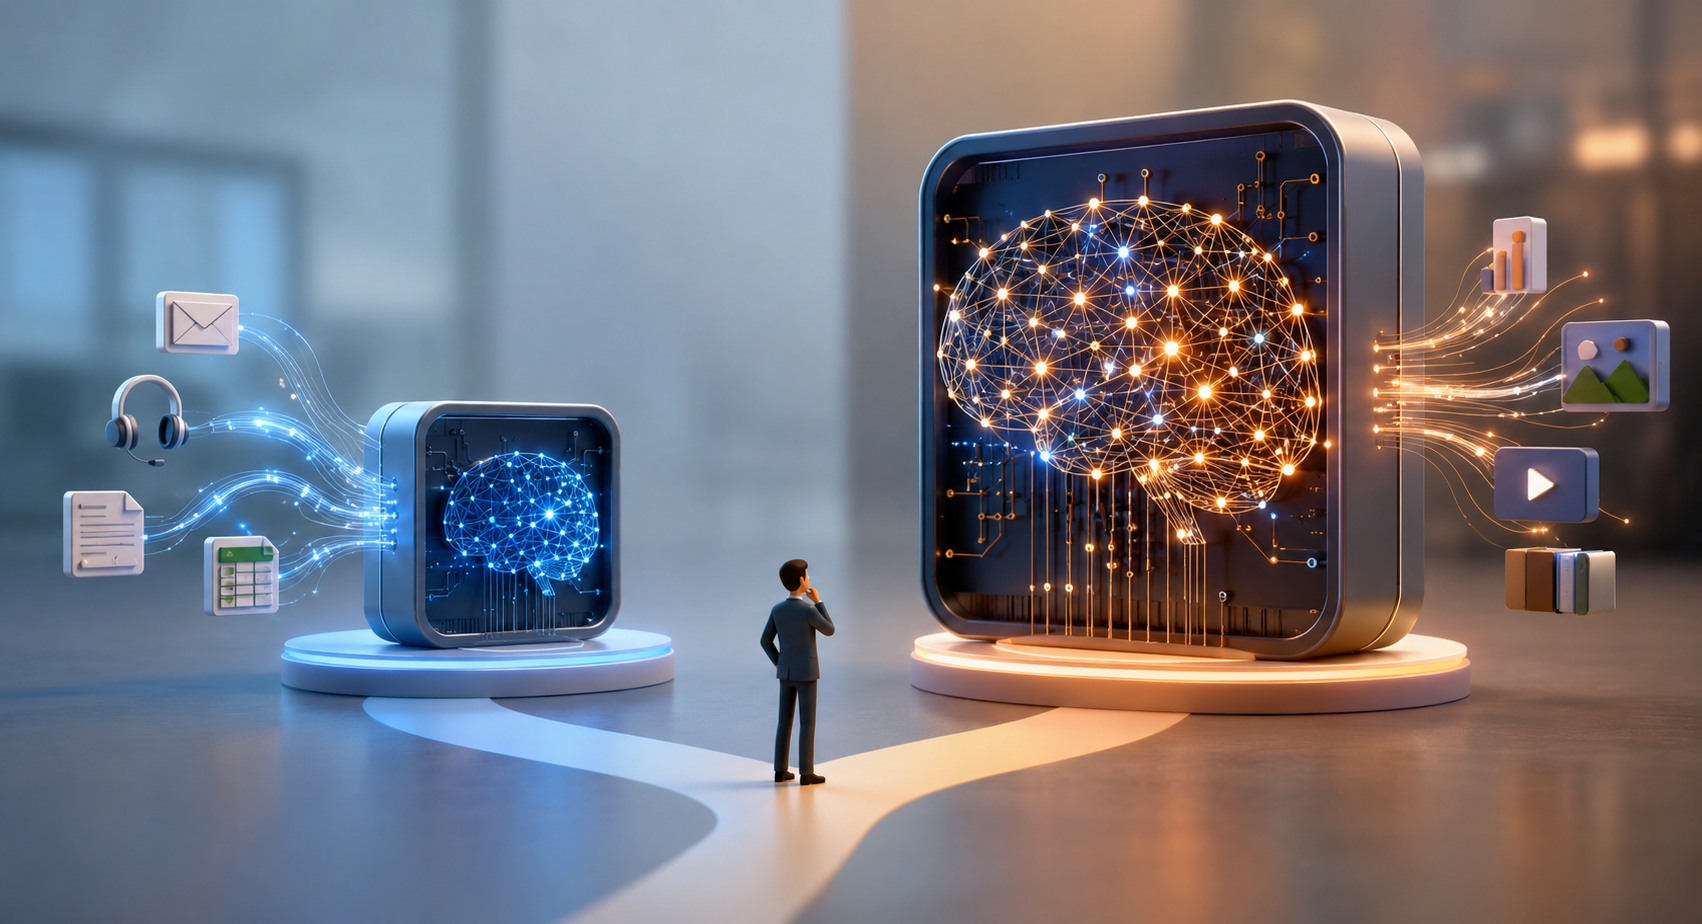
When a new frontier model tops the benchmarks, the reflex is to route everything through it, and that reflex quietly inflates cost, latency, and risk for workloads that never needed it. Most production tasks are narrow: classify a ticket, pull fields from an invoice, draft a templated reply. A model a fraction of the size can often handle them just as well, faster, and for a small fraction of the price. The real skill is no longer picking the most capable model; it is matching model size to the job in front of you.
This guide is for teams deciding which language model to put behind a feature or workflow. It answers:
A large language model (LLM) carries tens to hundreds of billions of parameters, broad world knowledge, and the ability to reason across many steps. It usually runs in a data center or behind a cloud API because it needs serious hardware. A small language model (SLM) is far more compact (often in the low single-digit billions of parameters, sometimes under a billion), small enough to run on a single GPU, a laptop, or increasingly a phone, and typically tuned for a focused range of tasks rather than everything at once.
The boundary is fuzzy and keeps moving as compression and training methods improve. What matters is not the exact parameter count but the trade-off each represents: breadth and reasoning depth on one side, and cost, speed, and deployability on the other.
A larger model is more capable in the general sense, but “more capable” is not the same as “better for your task.” Public benchmarks measure hard, open-ended reasoning: the kind of problem that separates frontier models from the pack. The trouble is that most business workloads look nothing like a benchmark. They are narrow, repetitive, and well understood: sort this message, extract these fields, summarize this record against a fixed template.
On a job like that, a small model prompted or fine-tuned for the task frequently matches a frontier model on quality while costing a fraction as much and answering several times faster. Paying frontier prices to classify support tickets is like chartering a freight plane to deliver a letter: it works, but you are buying capability the task never touches.
The two differ on far more than raw capability. These are the dimensions that decide most real-world choices.
| Dimension | Small language model | Large language model |
|---|---|---|
| Cost per request | Low: cents or less | High: scales with usage |
| Latency | Fast, often sub-second | Higher, grows with output length |
| Reasoning breadth | Narrow, best on focused tasks | Broad, strong multi-step reasoning |
| Accuracy on narrow tasks | Competitive when tuned | High, but often more than needed |
| Deployment | On-device, edge, or single GPU | Cloud or data-center GPUs |
| Privacy and hosting | Can run entirely in your environment | Often a third-party API |
| Best fit | High-volume, well-defined jobs | Open-ended, novel, or complex work |
Framing this as a single choice for the whole system is the mistake. The stronger pattern is hybrid routing, sometimes called model cascading, where each request goes to the smallest model that can handle it and escalates only when it must. A fast, cheap small model takes the request first. A lightweight check then decides whether the answer is trustworthy: a confidence score, a validation rule, or the model flagging its own uncertainty. Requests that clear the check are done; those that fail are retried on a larger model.
The economics are the whole point. In many workloads the small tier absorbs the large majority of easy, high-volume traffic, and the expensive model is reserved for the minority of hard cases that actually justify it. That collapses both average cost and average latency while preserving quality on the difficult tail. Routing is not free (you have to build the escalation logic, use evaluation to set the threshold, and monitor for drift as traffic changes), but for high-volume products the savings usually repay that effort quickly.
Size and intent. A large model has far more parameters and broad, general reasoning ability, but it needs powerful hardware and costs more per request. A small model is compact enough to run on modest hardware or a device, and is usually specialized for a focused set of tasks rather than trying to do everything.
Not on the work they are built for. On broad, open-ended reasoning a large model wins clearly. But on a narrow, well-defined task with good prompting or fine-tuning, a small model often matches a large one, and it does so faster and far more cheaply. Accuracy should be judged on your task, not on a general benchmark.
Yes, and that is one of their biggest advantages. Many small models run on a single GPU, a laptop, or a modern phone, which keeps data local, removes network latency, and lets a feature work without a connection. That makes them a strong fit for privacy-sensitive, regulated, or edge scenarios where sending data to a cloud API is undesirable.
No. Most mature systems use several. Hybrid routing sends each request to the smallest capable model and escalates only the hard cases to a larger one, so you get low cost and latency on the bulk of traffic and full capability where it matters. Picking a single model for everything usually means overpaying or underperforming somewhere.
Bigger models are more capable, but capability you never use is just cost, latency, and risk you pay for anyway. The question worth asking is not “which model is best?” but “what is the smallest model that reliably does this job?” For the narrow, high-volume tasks that make up most production work, the honest answer is often surprisingly small.
Right-sizing is not a one-time verdict either. Measure quality on your own task rather than a leaderboard, weigh cost and privacy alongside accuracy, and where volume is high, let a router send easy requests to a small model and reserve the large one for cases that truly need it. That is how you earn frontier quality where it counts without paying frontier prices everywhere else.
Start Your AI Journey
Whether you are exploring AI for the first time or scaling enterprise-wide initiatives, 3Shadz helps businesses design, develop, and deploy intelligent solutions that drive measurable results.