
Browse our current openings and find a role that matches your skills and ambition.
Know more ▸
Get a feel for our culture, our people and the way we work together every day.
Know more ▸
Health, flexibility and growth benefits designed to support you and your family.
Know more ▸

Kickstart your career with hands-on internship opportunities and mentorship.
Know more ▸

Written by 3Shadz Editorial Team
Moving data into the cloud is the easy part. Keeping it accurate, private, and defensible once it is scattered across object stores, warehouses, SaaS tools, and a dozen team-owned projects is the hard part, and it is where trust quietly erodes. When no one is certain who owns a dataset, who can read it, or whether it is even correct, every dashboard and decision downstream inherits that doubt. Data governance in the cloud is the discipline that turns a sprawling estate back into something an organization can rely on and stand behind in an audit.
This article is written for data, security, and technology leaders responsible for keeping cloud data safe and usable at the same time. You’ll come away understanding:
On-premises, data lived in a handful of known databases behind a single perimeter, and governance could lean on that scarcity. The cloud inverts it. Storage is cheap and self-service, so copies multiply, analysts spin up their own warehouses, pipelines fan the same records into new tables, and third-party SaaS platforms each hold a slice of the truth. The tidy perimeter dissolves, and sensitive data ends up in places no central team ever catalogued.
The shared responsibility model adds a subtlety that trips up many organizations. Your cloud provider secures the infrastructure (the data centers, the hardware, the hypervisor), but classifying what a dataset contains, deciding who may touch it, and proving compliance to a regulator all remain yours. Governance in the cloud is therefore not a product you buy and switch on. It is a set of controls you operate continuously across every account, region, and service you use.
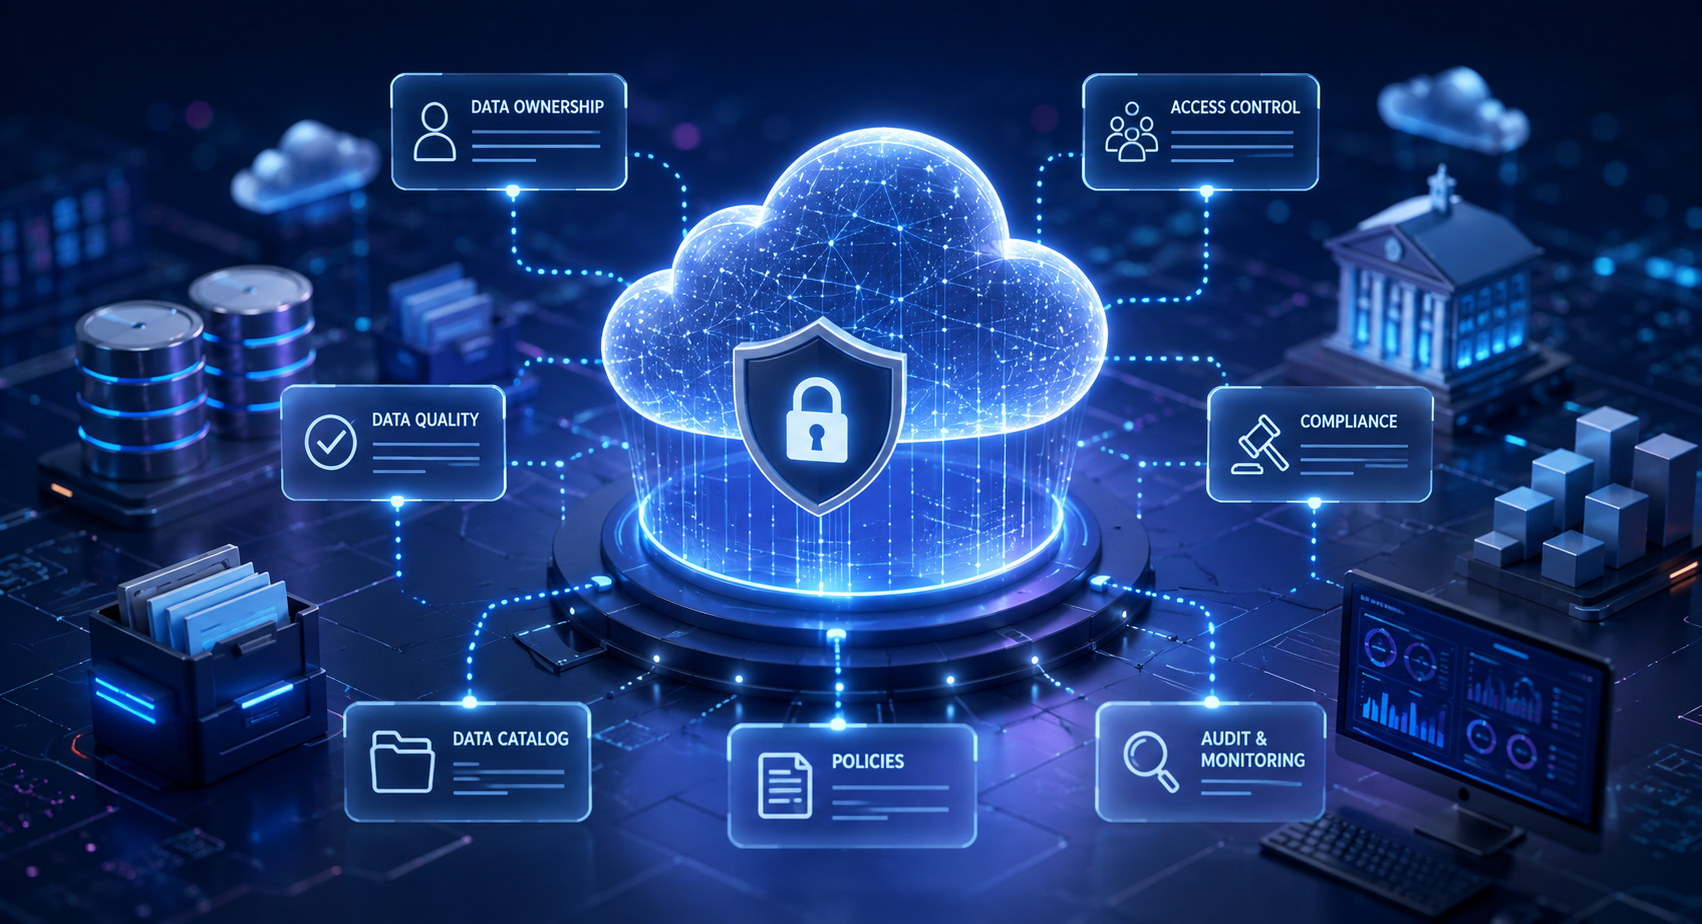
Effective governance is not one control but several working in concert. Each pillar closes a specific gap between data that merely sits in storage and data an organization can actually trust and defend.
A control can only protect data it knows exists. A data catalog inventories every dataset across your cloud accounts (what it is, where it lives, and what it means) and classification tags each one by sensitivity, from public and internal through confidential and regulated personal data. That label is the keystone. Masking rules, access policies, retention schedules, and residency controls all key off classification, so an uncatalogued or mislabeled dataset is one that every downstream control silently skips.
In the cloud, identity is the perimeter. Access should be granted by role or attribute against the minimum a person actually needs, not the maximum that is convenient. The recurring failure is the broad, permanent grant: a bucket left readable to a whole account, or a temporary permission that outlives the project by two years. Strong practice ties access to classification, prefers time-bound and just-in-time grants over standing ones, and reviews entitlements on a schedule so privilege shrinks back down instead of only ever growing.
Governance is not only about locking data down; it is about whether people can believe it. A number that is stale, incomplete, or silently duplicated erodes trust as surely as a leak does. This pillar assigns each significant dataset a named owner and a defined quality bar (expected freshness, completeness, and validity) and makes that bar visible to the people who consume the data. A trusted dataset is one that carries a known owner and a known standard, so users can tell certified data from a stray copy at a glance.
Lineage records where data originated, what transformed it along the way, and where it ultimately flows. When a figure looks wrong, lineage lets you trace it to the source instead of guessing. When a regulator asks how a reported number was derived, lineage is the answer. It also powers impact analysis, knowing which reports break if a source changes, and it is what makes a “delete this person’s data” request tractable, because you can actually find every place the record traveled.
Regulations such as GDPR, HIPAA, and CCPA-style laws impose concrete duties: obtain consent, honor the right to erasure, limit how long data is kept, and in some cases keep it inside a specific region. Governance encodes those duties into the platform rather than trusting people to remember them, masking and tokenization for sensitive fields, residency controls that pin data to a jurisdiction, and retention schedules that expire records automatically. The aim is that compliant behavior is the default, not a manual step someone has to perform under audit pressure.
The pillars above set the rules; monitoring proves they are being followed. Continuous logging of who accessed what, and where data moved, turns governance from a one-time snapshot into ongoing assurance. Anomaly detection flags the unusual (a service account suddenly reading a sensitive table, an export far larger than normal) while the audit trail gives you the evidence an examiner will ask for. Without this pillar, you are trusting that nothing has drifted since the last review.
Policies that live only in a document are ignored the moment they slow someone down. Governance that holds up in a real cloud environment moves the rules into the systems themselves, so following them is easier than working around them. That shift is what separates a governance program from a governance slide deck.
It is the set of controls that keep cloud data secure, compliant, and trustworthy (cataloging and classifying data, controlling who can access it, tracking its lineage, enforcing privacy rules, and monitoring use), operated continuously across every cloud account and service rather than set up once and forgotten.
The cloud removes the single perimeter governance used to rely on. Data spreads across many self-service services, regions, and SaaS tools, so controls must travel with the data through classification and identity rather than sitting at a network boundary. The shared responsibility model also means the provider secures the infrastructure while classification, access, and compliance stay your responsibility.
Done as manual approvals and paperwork, it does. Done as automated guardrails (a searchable catalog, classification-driven masking, and self-service access with expiry), it speeds teams up, because they can find and use trusted data without filing tickets or waiting on a central reviewer.
Responsibility is shared. The cloud provider secures the underlying platform, a central data or security team sets policy and provides the tooling, and each dataset needs a named business owner or steward accountable for its meaning, quality, and access. Governance works when those roles are explicit rather than assumed.
Modernize Your Cloud & Data
3Shadz helps businesses modernize cloud infrastructure and build secure, scalable data platforms that turn raw information into real-time insight and competitive advantage.