
Browse our current openings and find a role that matches your skills and ambition.
Know more ▸
Get a feel for our culture, our people and the way we work together every day.
Know more ▸
Health, flexibility and growth benefits designed to support you and your family.
Know more ▸

Kickstart your career with hands-on internship opportunities and mentorship.
Know more ▸

Written by 3Shadz Editorial Team
Most organizations no longer struggle to collect data; they struggle to get a trustworthy answer out of it fast enough to matter. The pipelines run and the warehouse fills, yet a regional manager still waits three days for a report a central team has to assemble by hand. Cloud-native data analytics is the layer that closes that gap: the point where stored data becomes an answer a decision-maker can act on, delivered at the speed the decision demands.
This article is written for business and technology leaders who want more from their data than backward-looking reports. You’ll come away understanding:
A modern data platform does an enormous amount of work before anyone sees a number, ingesting sources, storing them in a lake or warehouse, and transforming raw records into clean, reliable tables. All of that is invisible plumbing. Analytics is the last mile: the part a business user actually touches, where a curated table becomes a chart, a metric, a forecast, or an alert. When people say a data investment “isn’t paying off,” the pipelines are usually fine; the failure lives in this last mile: insight that arrives too slowly, reaches too few people, or that no one quite trusts.
For years that last mile ran on a scarce, central resource: a small analytics team writing queries on hardware that could serve only so many people at once. Requests queued for days. Cloud-native analytics rebuilds this layer on elastic infrastructure: compute that scales up for a heavy query and back down when idle, decoupled from where the data is stored. The practical effect is not only faster queries; it is that far more people can ask their own questions at the same time without competing for one machine or one team’s calendar.
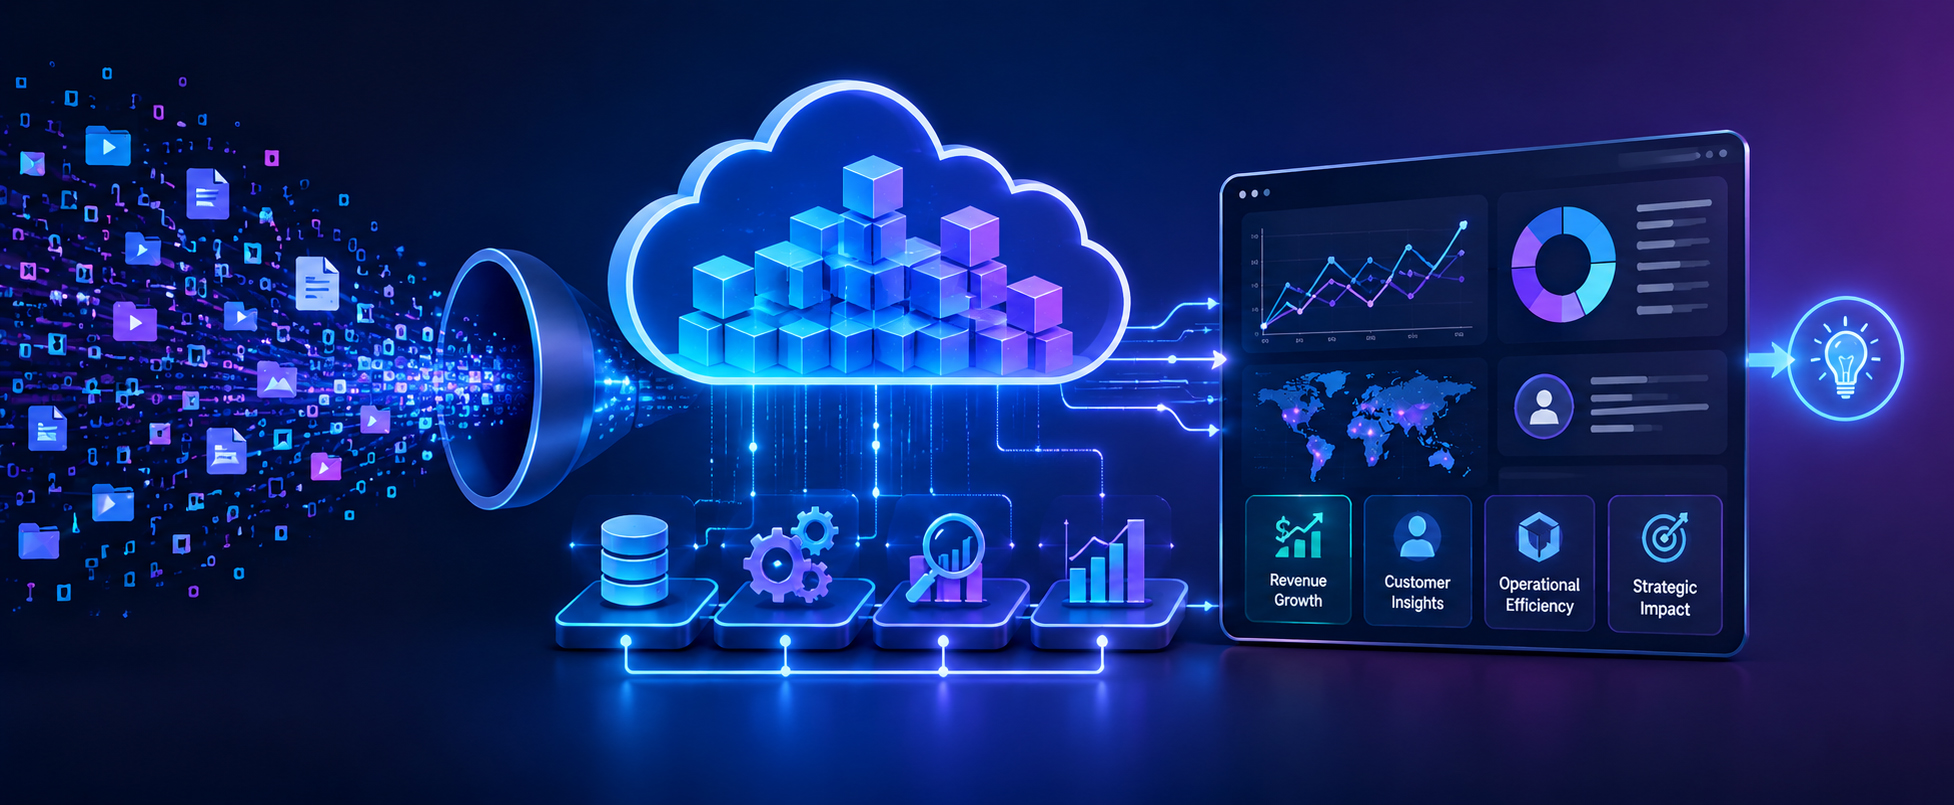
Underneath the dashboards, a handful of components do the work that makes analytics both scalable and self-serve. Knowing them helps leaders judge whether an analytics stack will hold up as usage grows.
Data sits once in inexpensive cloud storage, and multiple independent compute engines read it on demand. A finance team’s month-end crunch no longer slows the sales dashboard, because each workload gets its own elastic compute that spins up and then disappears. This decoupling is what allows analytics to scale to hundreds of concurrent users without contention and without paying for idle hardware between peaks.
Self-service only works if everyone’s numbers agree. A semantic layer defines shared metrics once, what “active customer” or “net revenue” actually means, so a spreadsheet, a dashboard, and a natural-language query all return the same figure. Without it, opening the data to everyone produces a room full of conflicting numbers and no agreed version of the truth.
Modern BI tools, and increasingly natural-language interfaces, let a business user filter, pivot, and drill into governed data without writing SQL or filing a ticket. The analyst’s role shifts accordingly, from producing every report by hand to curating the trustworthy datasets and metrics that others can safely explore on their own.
Insight has to reach the moment of decision. That might be a live dashboard, a metric embedded inside the application a user already works in, or an automated alert that fires the instant a threshold is crossed. The strongest analytics layers push answers toward people rather than waiting for them to log in and go looking.
The payoff appears wherever a faster, self-served answer changes what a team can actually do. Four patterns account for most of the value.
Business teams build and adjust their own views against governed data, answering routine questions themselves instead of queuing behind a central reporting team for every small change.
Live metrics on orders, inventory, or service levels let a team catch and correct a problem within the hour, rather than reading about it in tomorrow’s summary.
Charts and metrics placed directly inside a product or internal tool put relevant insight in front of customers and staff in context, with no detour to a separate reporting system.
Beyond describing what happened, cloud analytics runs forecasts and models (demand projections, churn risk, anomaly flags) and lets users pose a question in plain language and get an explained answer.
Opening analytics to everyone multiplies value, and it multiplies the ways things go wrong. The failure modes are predictable:
Guarding against those failures comes down to a few enablers that let scale and trust grow together rather than in tension.
It is analytics built to run on elastic cloud infrastructure and consumed as a self-service capability. Data stored once is queried by independent, on-demand compute, so many people can turn it into dashboards, metrics, and forecasts without waiting on a central team or a fixed server.
Traditional BI ran on fixed hardware and a small team that produced most reports, so requests queued. Cloud-native analytics separates storage from elastic compute and adds self-service tools and governed metrics, letting far more users explore trusted data at the same time.
No, it changes what the team does. Instead of hand-building every report, analysts and engineers curate trustworthy datasets, define shared metrics, and manage access and cost, so business users can safely answer their own routine questions.
A semantic layer defines business metrics once, what a term like “active customer” or “net revenue” means, so every dashboard, spreadsheet, and query returns the same number. It is what keeps self-service from producing a room full of conflicting figures.
Modernize Your Cloud & Data
3Shadz helps businesses modernize cloud infrastructure and build secure, scalable data platforms that turn raw information into real-time insight and competitive advantage.