
Browse our current openings and find a role that matches your skills and ambition.
Know more ▸
Get a feel for our culture, our people and the way we work together every day.
Know more ▸
Health, flexibility and growth benefits designed to support you and your family.
Know more ▸

Kickstart your career with hands-on internship opportunities and mentorship.
Know more ▸

Written by 3Shadz Editorial Team
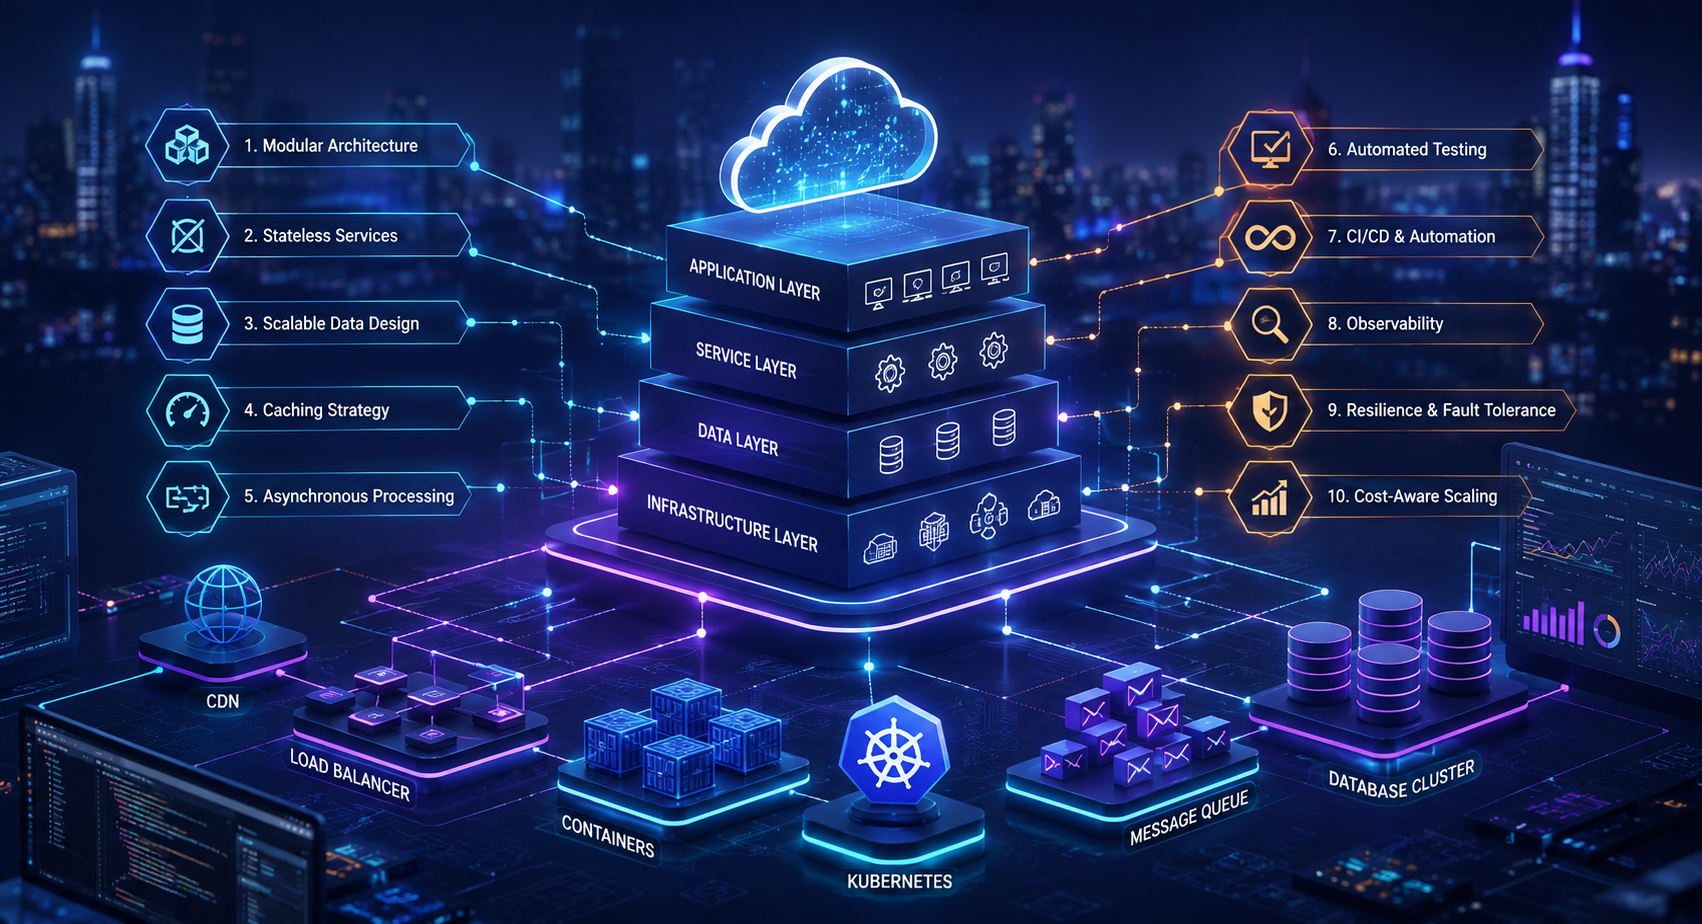
An application that runs beautifully for a hundred users can fall over at ten thousand, not because the code is wrong, but because it was never designed to spread its work out. Scalability is not a feature you bolt on after launch; it is a series of engineering decisions made deliberately, each trading a little added complexity for a lot more headroom. The techniques below are the ones that let a system absorb growth, and every one of them carries a cost worth naming before you reach for it.
Written for engineers and technical leaders who need an application to keep working as demand climbs, this guide focuses on mechanisms, not marketing. You’ll come away understanding:
Scalability is the ability of a system to handle more work (more users, more data, more requests per second) by adding resources, ideally without a rewrite. The operative word is adding. A system scales well when you can meet rising demand simply by giving it more hardware; it scales badly when the only remedy is a fundamental redesign carried out under pressure, after users are already feeling the pain.
There are two ways to add those resources, and the distinction shapes nearly every decision that follows.
| Dimension | Vertical scaling | Horizontal scaling |
|---|---|---|
| How capacity is added | A bigger, more powerful machine | More machines working in parallel |
| Ceiling | Limited by the largest hardware available | Effectively unbounded |
| Fault tolerance | One machine is a single point of failure | Redundancy across many instances |
| Cost pattern | Large, step-change upgrades | Incremental, pay as you grow |
| Complexity | Simple to run | Requires statelessness and coordination |
Reaching for a bigger machine is the easy first move, but a single machine always hits a ceiling. Almost everything else in this article is the discipline required to scale horizontally, to run many copies of an application at once and let them share the load.
These practices build on one another. Statelessness comes first because the rest depend on it, and observability comes last because it tells you which of the others you actually need.
Store nothing about a user’s session inside the application process itself: no in-memory session object, no uploaded file resting on local disk. When each instance holds no local state, any instance can serve any request, and you can add or remove instances freely. State moves to places built for it: a signed token in the request, a shared session cache such as Redis, object storage for files. The trade-off is an extra network hop to reach that shared state and the discipline of never quietly relying on local memory; the reward is that every technique after this one becomes possible.
Instead of buying a larger server, run many identical instances and place a load balancer in front to distribute requests across them. Capacity grows almost linearly as you add instances, and losing one no longer takes the whole system down. This depends entirely on statelessness: sticky sessions that pin a user to one instance are a warning sign that state leaked into the process. The cost is coordination: more parts to deploy, monitor, and keep consistent, and any workload that resists being split will see little benefit.
Caching stores the result of expensive work close to where it is needed so the work is not repeated. A CDN serves static assets from the edge, an in-memory cache holds hot query results, and computed values are kept rather than recalculated on every request. Done well, caching removes the majority of load from your database and origin servers. The hard part is invalidation, knowing when cached data has gone stale, and guarding against a stampede when many requests miss at the same moment; the wrong expiry window quietly trades correctness for speed.
Not everything has to finish while the user waits. Sending email, generating reports, resizing images, and syncing third-party systems can be pushed onto a message queue and handled by background workers. This keeps responses fast and lets the queue absorb traffic spikes that would otherwise overwhelm the system. The trade-off is eventual consistency (the work completes soon, not instantly) along with the operational weight of retries, idempotent handlers, dead-letter queues, and watching queue depth so a backlog never grows unnoticed.
Your database is usually the first component to buckle, because nearly every request touches it. Read replicas copy data to additional nodes so read-heavy traffic spreads across them, while partitioning, sharding, splits a large dataset across nodes by a key such as customer or region. Replicas introduce replication lag, so a read taken just after a write may return stale data; sharding makes cross-partition queries and joins harder and rebalancing painful. Because these are the costliest changes to reverse, the data model deserves the most thought up front.
A scalable system bends under extreme load rather than snapping. Rate limiting caps abusive traffic, circuit breakers stop hammering a dependency that is already failing, and feature flags let you shed non-essential functionality to protect the core path. A store that keeps checkout working while temporarily hiding personalized recommendations is degrading gracefully. The trade-off is deciding in advance what is essential and what is expendable, then building, maintaining, and testing those fallback paths so they actually hold up the day the surge arrives.
You cannot scale what you cannot see. Metrics, distributed tracing, and logs reveal where time and resources really go; load testing shows how the system behaves before live users find the breaking point for you; and autoscaling adds or removes capacity from those signals. The aim is to know your remaining headroom and act before you hit the wall, not after the pager goes off. The cost is genuine: instrumentation adds overhead, autoscaling reacts with a lag, and a dashboard is only as useful as the habit of reading it.
It means designing the system so you can meet rising demand by adding resources, usually more instances, rather than rewriting it under pressure. In practice that comes down to statelessness, horizontal scaling, caching, asynchronous processing, and a deliberate database plan, each chosen for the load you actually expect.
Vertical scaling means moving to a bigger, more powerful machine; it is simple but hits a hard hardware ceiling and leaves a single point of failure. Horizontal scaling means running many machines behind a load balancer; it reaches much further and adds redundancy, at the price of the complexity described throughout this article.
The database, more often than not, because almost every request reads or writes data. Caching reduces the pressure on it, read replicas spread reads across nodes, and partitioning divides the data itself, but the data layer nearly always needs attention before the application tier does.
No. Scalability comes from statelessness, caching, asynchronous work, and database techniques, all of which apply just as well to a well-built monolith. Microservices are an architectural choice with their own trade-offs; plenty of large systems scale comfortably on a single application replicated horizontally.
Build Better Software
From architecture to delivery, 3Shadz helps teams design, build, and scale reliable software with modern engineering practices, automation, and quality built in from day one.